Billy Brooks
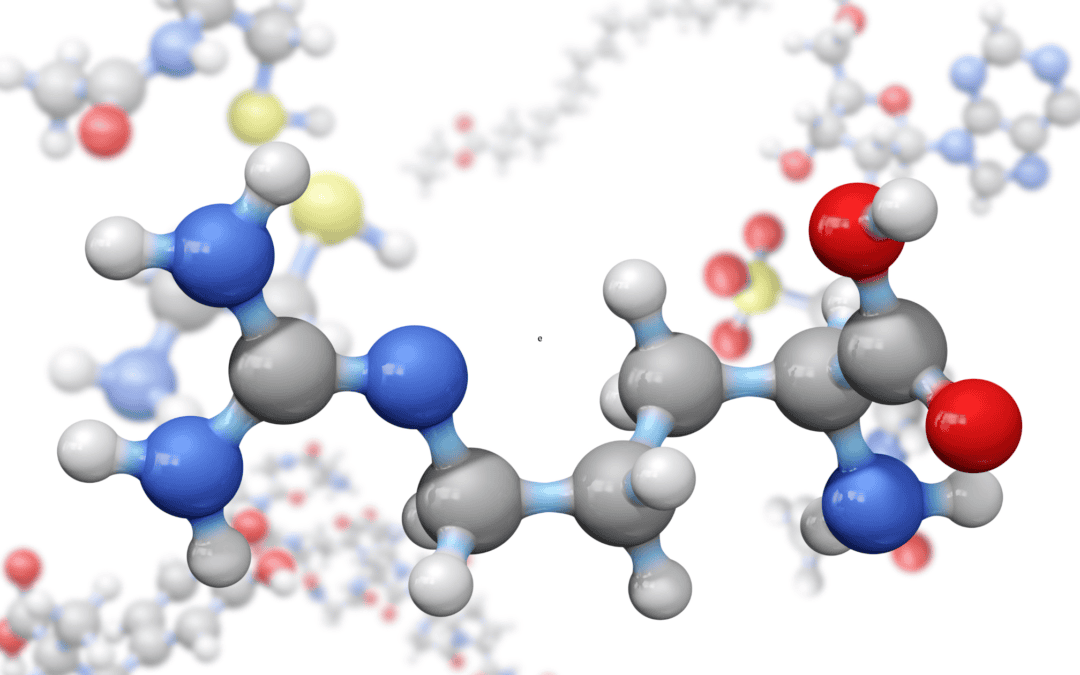
Sequencing data confirms one thing about the structural integrity of KPV, which is that the chain in the vial matches the intended build residue for residue. Purity figures state how much of a sample is one compound, while sequencing states that the compound itself is assembled correctly, so the two answers cover different ground. Studies documenting KPV peptide benefits in laboratory settings rest on sequencing confirmation at the base of their files, since every observed effect is attributed to a specific molecular arrangement. The sections below cover the sequencing data itself, the structural properties the data confirms, and the reading practice that turns a returned report into a standing confirmation of integrity.
KPV sequencing data
KPV sequencing data covers the complete chain, from the first residue to the last, including the bonds joining them.
- Data of this kind contains the identified residue at each position, the measured evidence supporting each identification, and a coverage statement showing how much of the chain the analysis reached. Full coverage means every position was read rather than inferred, and research use expects nothing less.
- Sequencing output at its smallest unit is one line stating a position number, the residue found there, and the confidence attached to the finding, which is the level of detail the whole document is built from.
Peptide integrity confirmation
Peptide integrity confirmation rests on four structural properties that the data establishes.
- Residue identity – Confirmation establishes that each position holds its intended residue, with lysine, proline, and valine each read at the correct place. A substitution anywhere in the chain shows up as a mismatch at that position.
- Bond formation – Confirmation extends to the linkages, verifying the residues are joined through proper peptide bonds rather than alternative connections a synthesis error could leave behind.
- Terminal state – Confirmation covers both chain ends, establishing that the termini carry their expected chemistry and that no truncation or unintended modification sits at either one.
- Absence of rearrangement – Confirmation rules out sequence scrambling, since a chain holding the right residues in the wrong order produces a distinct analytical signature that the data would expose.
Structural confirmation reading
Structural confirmation is read in a fixed order when the report arrives, starting with the coverage statement, moving to the position table, and finishing at the confidence column, because a report with gaps in coverage confirms only the sections it reached. A reader finding full coverage, matched residues at every position, and confidence values within the accepted range holds a document stating the compound’s integrity outright. Confirmation reading continues as the report enters the archive. The document gets filed against its batch number, cross-referenced to the certificate, and dated, and from that point it serves the study as the standing answer to any structural question a reviewer later raises.
Sequencing data confirms the structural integrity of KPV by establishing residue identity, bond formation, terminal state, and correct order in one analysis, and the confirmation carries a weight that no other document in the research file matches. Having a compound that is intact at every position gives the study a foundation that can be reviewed, replicated, and supported by the eventual findings. As a result of teams filing sequencing confirmation at the beginning of a program, the integrity question is settled once, completely, and in writing. This is why the practice has become commonplace whenever the compound’s structure carries significant meanings, and the report is a must-have alongside the certificate in any serious research project.
 Kenneth Martinez